Retrieval-augmented generation earned its place as a default architecture for enterprise AI for a good reason: it works. By grounding responses in retrieved documents, RAG can reduce unsupported answers and connect each claim to a real source.
That traceability matters in healthcare, fintech, life sciences, and other regulated sectors. Yet RAG is not a compliance control by itself. A trustworthy AI data pipeline also needs secure retrieval, permission-aware access, reliable citations, continuous evaluation, and defined human accountability.
In 2026, the industry is becoming more honest about where RAG’s guarantees end. For teams building AI into HIPAA, SOC 2, or GDPR-governed systems, that honesty is more useful than the hype that preceded it.
The core mechanism is simple. Instead of relying only on knowledge learned during training, a RAG system retrieves relevant documents before generating an answer. The model then uses that evidence as context.
Done well, this design produces answers that are current, correctable, and linked to source material. In addition, teams can update the knowledge base without retraining the foundation model. As a result, reviewers can inspect the evidence behind an answer rather than accepting a black-box assertion.
The National Institute of Standards and Technology used RAG for an internal chatbot that searches cybersecurity guidance. Its report describes the benefits of focused retrieval, but it also addresses prompt injection, hallucinations, data exposure, and unauthorized access. That combination captures the real enterprise proposition: better grounding with a new set of system-level responsibilities.
For regulated organizations, source traceability is close to a prerequisite. However, a visible citation is only the beginning. The system must also prove that the cited passage supports the claim, that the user was authorized to retrieve it, and that the source was valid at the time of the answer.
RAG reduces hallucination risk; it does not eliminate it. Failures often begin in retrieval rather than generation. For example, the system may fetch an irrelevant chunk, miss a decisive exception, retrieve an outdated policy, or combine claims that came from unrelated documents.
A 2026 study in npj Health Systems tested one clinical RAG system by repeating the same medication question under different conversation lengths. The hallucination rate was 5% with no prior dialogue and 40% after ten preceding exchanges. The researchers traced the degradation mainly to contextual drift in retrieval.
Those figures are not a universal RAG benchmark. The study used one architecture, one simulated clinical scenario, and automated evaluation. Still, the result demonstrates an important failure mode: a system that performs well on isolated questions may become unreliable as conversational history accumulates.
Multi-step questions create another challenge. Research on MultiHop-RAG found that existing systems struggled when they had to retrieve and reason across several pieces of evidence. Consequently, each missed document or incorrect connection can weaken the final answer. Therefore, single-document accuracy should not be treated as proof that a pipeline can support regulatory or clinical reasoning.
Confidence-aware retrieval and abstention. A reliable system must be able to say that evidence is missing, conflicting, or below a defined threshold. In clinical and financial workflows, a well-routed abstention is often safer than a fluent guess.
Continuous evaluation. Retrieval quality can change as documents, chunking rules, embedding models, re-rankers, and prompts evolve. Teams should evaluate retrieval relevance, answer faithfulness, citation correctness, and task outcomes on an ongoing basis. Multi-turn, adversarial, and low-coverage cases belong in the test set.
Modular, versioned architecture. Retrieval, indexing, re-ranking, generation, orchestration, and validation should remain separable. That makes it possible to upgrade one component without rebuilding the system. It also makes every production answer reproducible against the document, embedding, index, prompt, and model versions that produced it.
Permission-aware retrieval. A vector database must enforce the same access boundaries as the source systems. Moreover, the OWASP guidance on vector and embedding weaknesses warns that weak controls can expose sensitive information, leak data across tenants, or allow poisoned content to manipulate outputs.
Data quality and lineage. Enterprise reliability problems often begin before a model sees the query. Duplicate policies, broken parsing, stale documents, missing metadata, and ambiguous ownership all degrade retrieval. Every chunk should retain its source, effective date, classification, owner, and transformation history.
In regulated industries, the business case for RAG is often its evidence trail. A system that shows which document supported which claim can answer questions that an ungrounded model cannot. However, that trail is defensible only when governance begins at ingestion.
For healthcare, the HIPAA minimum necessary standard generally requires reasonable steps to limit uses, disclosures, and requests for protected health information. A RAG pipeline should therefore filter retrieval by identity, role, purpose, and patient context before sensitive chunks enter the model’s context window.
The HIPAA Security Rule also requires regulated entities to assess risks, manage access, and review system activity. That makes retrieval logs, authorization decisions, exception events, and administrative actions part of the compliance surface—not optional debugging data.
Under GDPR Article 5, purpose limitation, data minimization, accuracy, and storage limitation should influence what enters the index and how long it remains there. Embeddings should not be treated as anonymous merely because they are numerical representations.
For SOC 2 programs, the AICPA Trust Services Criteria focus attention on security, availability, processing integrity, confidentiality, and privacy. RAG changes which components and vendors fall inside that control environment. It does not remove the need to demonstrate that controls operate effectively.
Start by defining the decisions the system may support and the decisions it may not make. Then map the authoritative sources, data owners, retention rules, and access policies for each use case.
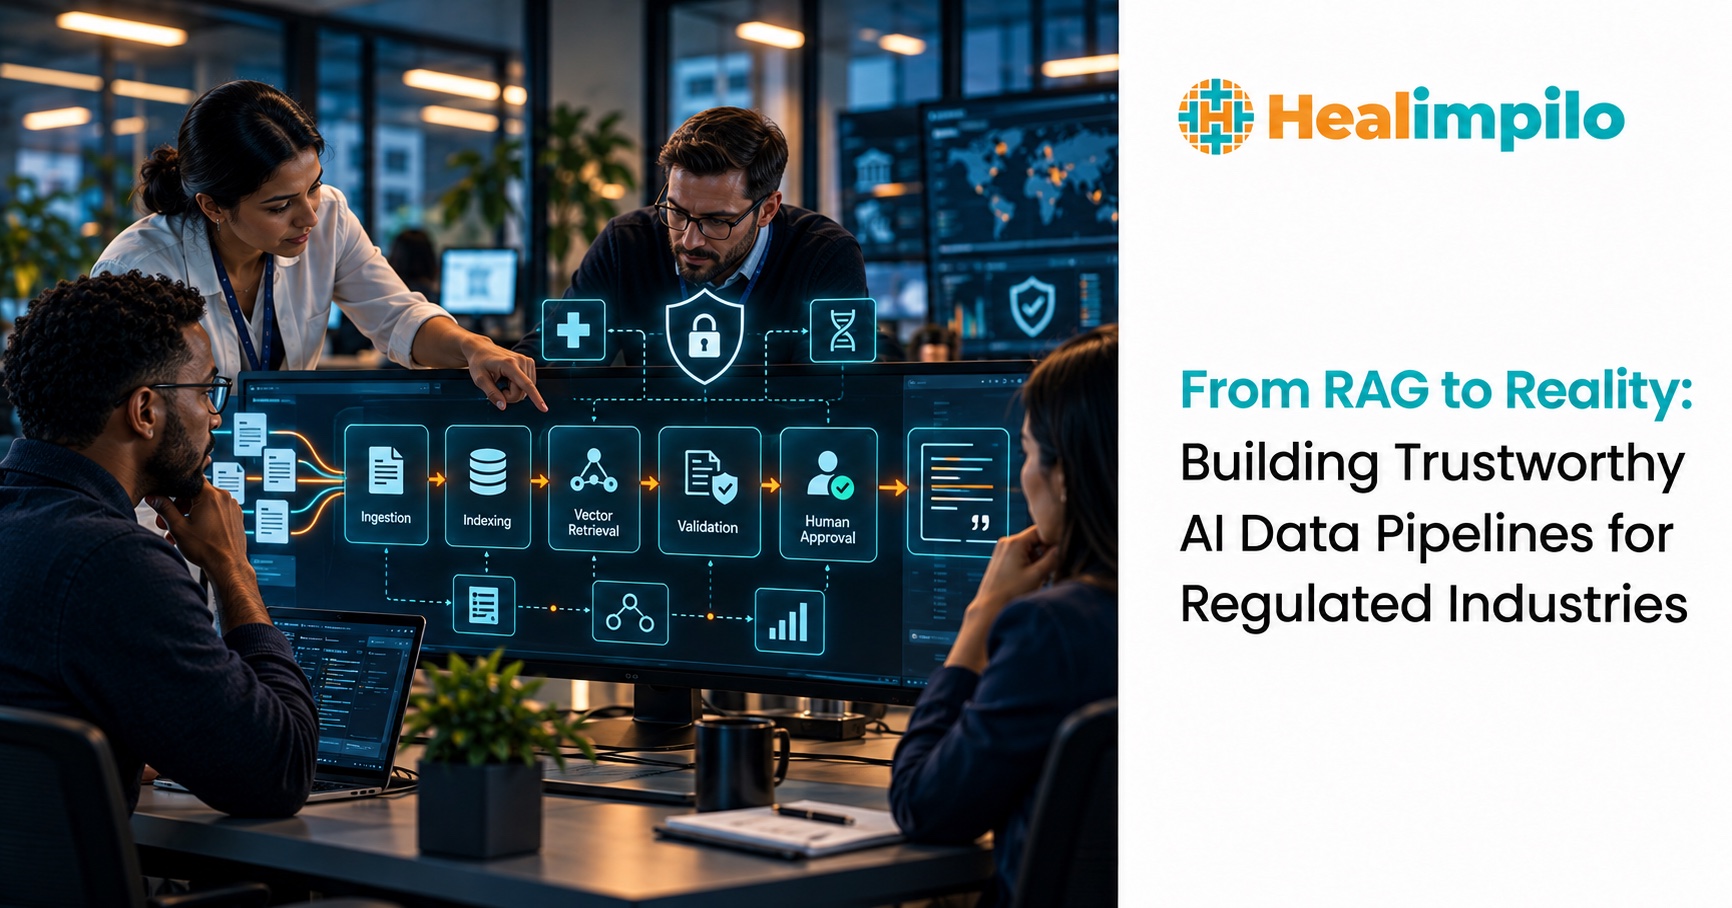
Next, build an evaluation set from real work. Include ordinary questions, missing-answer cases, conflicting policies, outdated sources, multi-step reasoning, long conversations, and adversarial documents. Measure the retriever and generator separately so a good final answer does not hide weak evidence selection.
In production, log the query, retrieved document identifiers, relevance scores, access decision, model and prompt versions, citations, output, and human disposition. Protect those logs according to the sensitivity of the underlying data. Alert on retrieval drift, rising abstention, citation failures, and changes after re-indexing.
Finally, define a human review gate for outputs with clinical, financial, legal, or safety consequences. Reviewers need the source passage, document version, and system confidence—not only the generated prose. Their corrections should feed the evaluation program rather than disappear into an operational queue.
RAG is not a solved problem. Treating it as one is how organizations end up with a governance failure dressed as a technical success.
Treated as a discipline, however, RAG can provide the foundation regulated AI needs. It can connect answers to evidence, keep knowledge current, and make failures easier to investigate. The difference lies in the pipeline around the model: governed data, secure retrieval, measurable quality, reproducible decisions, and accountable human oversight.
For a related look at the controls embedded teams need as AI moves into operational workflows, read Agentic AI in Healthcare IT: Preparing Embedded Teams for the Next Wave of Automation.
Healimpilo is a technology advisory firm working with companies across healthcare, fintech, life sciences, and SaaS on engineering strategy, talent, and delivery.